Field of Science

Findings: The Role of World Knowledge in Pronoun Interpretation

A few months ago, I posted the results of That Kind of Person. This was the final experiment in a paper on pronoun interpretation, a paper which is now in press. You can find a PDF of the accepted version here.

How it Began

Isaac Asimov famously observed that "the most exciting phrase to hear in science, the one that heralds new discoveries, is not 'Eureka!' but 'That's funny...'" That quote describes this project fairly well. The project grew out of a norming study. Norming studies aren't really even real experiments -- they are mini experiments used to choose stimuli.

I was designing an ERP ("brain wave") study of pronoun processing. A group in Europe had published a paper using ERPs to look at a well-known phenomenon in pronoun interpretation, one which has been discussed a lot on this blog, in which pronoun interpretation clearly depends on context:

(1) Sally frightens Mary because she...
(2) Sally likes Mary because she...

Most people think that "she" refers to Sally in (1) but Mary in (2). This seems to be a function of the verbs in (1-2), since that's all that's different between the sentences, and in fact other verbs also affect pronoun interpretation. We wanted to follow up some of the previous ERP work, and we were just choosing sentences. You get nice big ERP effects (that is, big changes in the brain waves) when something is surprising, so people often compare sentences with unexpected words to those with expected words, which is what this previous group had done:

(3) Sally frightens Bill because she...
(4) Bill frightens Sally because she...

You should get the sense that the pronoun "she" is a bit more surprising in (4) than in (3). Comparing these sentences to (1-2) should make it clear why this is.

The Twist

A number of authors argued that what is going on is that these sentences (1-4) introduce an explanation ("because..."). As you are reading or listening to the sentence, you think through typical causes of the event in question (frightening, liking, etc.) and so come up with a guess as to who is going to be mentioned in the explanation. More good explanations of an instance of frightening involve the frightener than the frightenee, and more good explanations of an instance of liking involve the like-ee than the liker.

The authors supported the argument by pointing to studies showing that what you know about the participants in the event matters. In general, you might think that in any given event involving a king and a butler, kings are more likely to be responsible for the event simply because kings have more power. So in the following sentence, you might interpret the pronoun as referring to the king even though it goes against the "typical" pattern for frighten (preferring explanations involve the frightener).

(5) The butler frightened the king because...

What got people particularly excited about this is that it all has to happen very fast. Studies have shown that you can interpret the pronoun in such sentences in a fraction of a second. If you can do this based on a complex inference about who is likely to do what, that's very impressive and puts strong constraints on our theory of language.

The Problem

I was in the process of designing an ERP experiment to follow up a previous one in Dutch that I wanted to replicate in English. I had created a number of sentences, and we were running a simple experiment in which people rate how "natural" the sentences sound. We were doing this just to make sure none of our sentences were weird, since that -- as already mentioned -- can have been effects on the brain waves, which could swamp any effects of the pronoun. Again, we expected people to rate (4) as less natural than (3); what we wanted to make sure was that people didn't rate both (3) and (4) as pretty odd. We tested a couple hundred such sentences, from which we would pick the best for the study.

I was worried, though, because a number of previous studies had suggested that gender itself might matter. This follows from the claim that who the event participants are matters (e.g., kings vs. butlers). Specifically, a few studies had reported that in a story about a man and a woman, people expect the man to be talked about more than the woman, analogous to expecting references to the king rather than the butler in (5). Was this a confound?

I ran the study anyway, because we would be able to see in the data just how bad the problem was. To my surprise, there was no effect of gender at all. I started looking at the literature more carefully and noticed that several people had similarly failed to find such effects. One paper had found an effect, but it seemed to be present in only a small handful of sentences out of the large number they had tested. I looked into studies that had investigated sentences like (5) and discovered ... that they didn't exist! Rather, the studies researchers had been citing weren't about pronoun interpretation at all but something else. To be fair, some researchers had suggested that there might be a relationship between this other phenomenon and pronoun interpretation, but it had never been shown. I followed up with some experiments seeing whether the king/butler manipulation would affect pronoun interpretation, and it didn't. (For good measure, I also showed that there is little if any relationship between that other phenomenon and pronouns.)

A Different Problem

So it looked like the data upon which much recent work on pronouns is built was either un-replicable or apocryphal. However, the associated theory had become so entrenched, that this was a difficult dataset to publish. I ultimately had to run around a dozen separate experiments in order to convince reviewers that these effects really don't exist (or mostly don't exist -- there do seem to be a tiny percentage of sentences, around 5%, where you can get reliable if very small effects of gender). (A typical paper has 1-4 experiments, so a dozen is a lot. Just in order to keep the paper from growing to an unmanageable length, I combined various experiments together and reported each one as a separate condition of a larger experiment.)

Most of these experiments were run on Amazon Mechanical Turk, but the final one was run at GamesWithWords.org and was announced on this blog (read the results of that specific experiment here). The paper is now in press at Language & Cognitive Processes. You can read the final submitted version here.

Conclusion

So what does all this mean? In many ways, it's a correction to the literature. A lot of theoretical work was built around findings that turned out to be wrong or nonexistent. In particular, the idea that pronoun interpretation involves a lot of very rapid inferences based on your general knowledge about the world. That's not quite the same thing as having a new theory, but we've been exploring some possibilities that no doubt will be talked about more here in the future.
----

Joshua K. Hartshorne (2014). What is implicit causality? Language and Cognitive Processes

Everlasting Love

I just got back data from a survey in which we asked people to estimate how long different emotions are likely to last. We'll use this information to design a future experiment looking at how people expect emotions to be encoded in language. In the meantime, what struck me is that of all the emotions we asked about, the one that people expected to last the longest was "being head-over-heels in love". Which is awesome.


(Image courtesy of Faizal Sharif)

New Experiment: The Vocab Quiz

Curious how good your vocabulary is? I just posted a new experiment that will tell you. There are 32 questions. At the end, you'll see your score and how it compares with others who have done the experiment. This should be a fairly hard test. I piloted it on around 40 people, and only a few managed to get all the questions right. Then I made it harder. You can find the experiment here.

What is the purpose of the experiment?

We are interested in why some people have better vocabularies than others. So before you take the test, you'll answer some questions about your background, such as your age, level of education, and birth order. The predictions for age and level of education are probably fairly obvious. The predictions for birth order are less clear. Some researchers would predict that eldest children will have better vocabularies (they spent more time with their parents and so got a jump start). Others would predict that the youngest would have better vocabularies (they had extra teachers in the home!). Still other researchers would argue that birth order (being the oldest or youngest, etc.) should have no effect on vocabulary, because they argue that pretty much nothing is affected by birth order.

We are particularly interested in people for whom English is a second language. What factors lead some people to easily acquire a second language and others not?

Take the Vocab Quiz.


New Experiment: The Language & Memory Test

There is a close relationship between language and memory, since of course whenever you use words and grammar, you have to access your memory for those words and that grammar. If you couldn't remember anything, you couldn't learn language to begin with.

The relationship between language and memory is not well understood, partly because they tend to be studied by different people, though there are a few labs squarely interested in the relationship between language and memory, such as the Brain and Language Lab at Georgetown University.

This week, I posted a new experiment, "The Language & Memory Test", which explores the relationship between memory and language. The experiment consists of two components. One is a memory test. At the end, you will see your score and how it compares with other people who took the test. This test is surprisingly hard for how simple it seems.

In the other part, you will try to learn to use some new words. We'll be studying the relationship between different aspects of your memory performance and how you learn these new words. As always, there will be a bit more explanation at the end of the experiment. When the experiment is done and the results are known, there will be a full description of them and what we learned here at the blog and at GamesWithWords.org.

Try the Language & Memory test here.

New Experiment: Collecting Fancy Art

Over the last few years, we've run a lot of experiments online at GamesWithWords.org, resulting so far in four publications, with a number of others currently under review at various journals. Most of these have experiments have focused on how people process and interpret language. I just posted a new experiment (Collecting Fancy Art) that is more squarely focused on learning language. Language learning experiments are somewhat tricky to do online, since they tend to take longer than the 5-10 minute format of online experiments, but they are important.

One of the most salient truths about language is that language has to be learned. This is clearly pretty hard, or other animals would be able to do it and we'd already have computers that were pretty good at language. But just how the learning process happens is a bit of a mystery, partly because language is a complex, interconnected system. When you learn one word, it affects how you use other words.

In this experiment, you will simultaneously learn the meanings of three different words. We're interested in seeing how your understanding of these words develops. As always, you'll learn more about the experiment at the end. And check back here in the future: After the experiment is completed, the results will be posted here.

The experiment is called "Collecting Fancy Art". You can find it here.

Lab Notebook: Social Networking

The problem with websites is they quickly become obsolete. A few years ago, I updated the website to make it easier to share pages, adding buttons for Facebook, Twitter, Digg, and Reddit. A little while ago, I noticed that the Digg button wasn't working anymore. Then the Twitter button disappeared. 

I just updated the website, switching from native buttons for social networking systems to ShareThis. ShareThis has the advantage of incorporating every social networking system you've heard of and a bunch you haven't heard of (I've put Google+, Facebook, Twitter, Tumblr, and email up front, but by clicking on the ShareThis button, users can choose from dozens of networks). 

Fieldofscience (the network this blog is a part of) has been using ShareThis for a couple years. However, it went through several periods where it wasn't working. Periodically, it would have memory failures, and posts that had once had dozens of likes suddenly went to zero. But lately it seems much more stable, so I'm trying it out.

The disadvantage is that every page says that it hasn't been liked by anybody, which isn't great advertising for the website. (*UPDATE* We've got a few shares now on some of the pages.) I hope this changes quickly.

The $64,000 question is, of course, whether this update changes the overall amount of traffic to the website. It's been averaging around 2,000 visitors/month for a couple years now. That's very respectable for a research website. However, many of the experiments now running (like the Mind Reading Quotient and Finding Explanations) require large numbers of participants, and they would really benefit from an uptick in traffic.

Who you gonna believe: E. O. Wilson or common sense?

I was planning a post on E. O. Wilson's recent flight of fancy, "Great Scientist ≠ Good at Math", in which he tells potential future scientists that knowing math isn't all that important, but it turns out Jeremy Fox has already said everything I was going to say, only better. It's a long post, though, so here are some key passages:
Wilson’s claim that deep interest in a subject, combined with deep immersion in masses of data, is sufficient, because hey, it worked for Charles Darwin, is utter rubbish. First of all, just because it worked for Darwin (or Wilson) doesn’t mean it will work for you, and just because it worked in the 19th century doesn’t mean it will work in the 21st. If for no other reason than that there are plenty of people out there, in every field, who not only have a deep interest in the subject and an encyclopedic knowledge of the data, but who know a lot of mathematics and statistics.
and

Wilson claims that strong math skills are relevant only a few disciplines, like physics. Elsewhere, great science is a matter of “conjuring images and processes by intuition”... I’m sure Wilson is describing his own approach here, and it’s worked for him. But I have to say, it’s surprising to find someone as famous for his breadth of knowledge as E. O. Wilson generalizing so unthinkingly from his own example. I wonder what his late collaborator Robert MacArthur would think of the notion that intuition alone is enough. I wonder what Bill Hamilton would think. Or R. A. Fisher. Or J. B. S. Haldane. Or Robert May. Or John Maynard Smith. Or George Price. Or Peter Chesson. Or Dave Tilman. Or lots of other great ecologists and evolutionary biologists I could name off the top of my head. Would Wilson seriously argue that none of those people were great scientists, or that they never made any great discoveries, or that the great discoveries they made arose from intuition unaided by mathematics?
Meanwhile, over at Finding the Next Einstein, Jonathan Wai draws on his own research to argue that mathematics ability is key to success in a wide range of scientific fields (though these data are unfortunately correlational).

International Journal of Lousy Research

Jeffrey Beall's blacklist of "predatory open-access journals" -- discussed in yesterday's New York Times -- provides evidence for my long-standing suspicion of any journal named "International Journal of ..." There probably are some good journals named "International Journal of...", but I don't know of any off-hand. And there seem to be an awful lot of bad ones, probably for good reason: An internationally-recognized journal doesn't have to say so. So almost by definition a journal that has to call itself "International Journal of" is probably not a well-known journal.

In general, nearly every journal on the list has some location in its name, such as South Asian Journal of Mathematics, which doubles down by referring to itself on its home page as an "international journal". Again, there are, of course, good journals with region-specific names. But there don't seem to be many. I'm less sure of the reason for this one.

[Future Post: Explaining why universities that market themselves as "The Harvard of" some region are frequently not even the most prestigious school in that region.]

Laying to rest an old myth about Chinese

I just got back from my second research trip to Taiwan in three years (with another planned soon!) and fourth trip overall. As always, I had a great time and ate as much beef noodle soup as I could manage.


As always, I spent a couple months beforehand brushing up my reading and writing. This isn't something I have to do before trips to Spain or Russia. A few hours spent learning Spanish or Russian orthography, and you are set for life. As soon as I blink, I forget how to read and write Chinese. This is because, as is well known, rather than a couple dozen phonetic symbols, Chinese employs thousands of easily-confusable characters which, if you don't use for a while, you end up confusing.

This isn't just a problem for foreigners. Students in Taiwan (and China or Japan, I assume) continue investing significant amounts of time into learning to read and write additional characters well through secondary school. This raises the question of why Chinese-speakers don't just adopt a phonetic writing system?

Problems with a Chinese phonetic writing system

The argument one often hears is that Chinese has so many homophones (words that sounds like), that if you wrote them all the same way, there would be so much ambiguity that it would be impossible to read. The character system solves this by having different characters for different words, even ones that sound alike.

In the last century, when switching to a phonetic system was proposed, a scholar illustrated this problem with the following poem, which reads something like this:
Shi shi shi shi shi shi, shi shi, shi shi shi shi. Shi shi shi shi shi shi shi shi shi, shi shi shi shi shi, shi shi, shi shi shi shi shi. Shi shi shi shi shi, shi shi shi, shi shi shi shi shi shi. Shi shi shi shi shi shi, shi shi shi. Shi shi shi, shi shi shi shi shi shi. Shi shi shi, shi shi shi shi shi shi shi shi. Shi shi shi shi shi shi shi shi shi shi shi shi shi. Shi shi shi shi.
As written, this is incomprehensible. Only if you write it in characters
the meaning becomes clear:
A poet named Shi lived in a stone house and liked to eat lion flesh and he vowed to eat ten of them. He used to go to the market in search of lions and one day chanced to see ten of them there. Shi killed the lions with arrows and picked up their bodies carrying them back to his stone house. His house was dripping with water so he requested that his servants proceed to dry it. Then he began to try to eat the bodies of the ten lions. It was only then he realized that these were in fact ten lions made of stone. Try to explain the riddle.
Problems with this argument

This argument sounds compelling until you realize that what is being claimed is that you can't understand a Chinese sentence based on its sound alone. This means that not only is it impossible to understand phonetically-written Chinese, it is impossible to understand spoken Chinese (which, like phonetically-written Chinese, doesn't have any characters to help disambiguate similar-sounding words). Since a billion people speak Mandarin Chinese every day, there must be a problem with this argument!

There are a few. First of all, I wrote the poem phonetically ignoring the five Chinese tones. Like many languages, Chinese uses intonation phonetically -- an 'i' with a rising tone is different from an 'i' with a falling tone. Writing a tonal language without tones is like writing English without vowels -- much harder to read. Similarly, the phonetic writing above does not have any breaks between words, making it much harder to read (imaginewritingEnglishwithoutspacesbetweenwords). True, written Chinese doesn't mark word boundaries, but then it has all the extra information encoded in the characters to help with any ambiguity.

Second, this poem uses very archaic Chinese (different vocabulary and different grammar than modern Mandarin). It's not clear how many people would understand the poem spoken aloud. Wikipedia gives a nice translation of the poem into modern Mandarin, which involves many different sounds, not just 'shi'.

The most important problem is that there actually is a perfectly good phonetic system for writing Chinese. Actually, there are several, but the most common is pinyin. People can and do write entire texts in pinyin.

Why care? 

Why go to the effort of debunking this myth? This often comes up in arguments over whether the Chinese should adopt a new writing system, but that's not really my concern. Very often, there is a tendency to believe that different cultures and languages are much more different from one another than they are. One hears about strange aspects of other languages without even pausing to think about the fact that your own language has many of those same features. The writing systems of English and Chinese are actually alike in many ways (both are partially phonetic and partially semantic -- a topic for a different post). I can only speak for myself, but the more I learn about a given language, usually the less foreign it seems. Which is a fact worth thinking about.

Update on DuoLingo

I have been using Duolingo for a few months to brush up my Spanish. I have generally found it to be pretty useful and a significant improvement over my strategy was to listen to the news in Spanish. So I was interested to see a report on the effectiveness of Duolingo.

Even though most people enrolled in the study did not actually spent much time using DuoLingo (only a handful managed more than 30 hours in two months), there was a statistically significant improvement. How much improvement? The report estimates that a person with no prior knowledge of Spanish would be able to place into 2nd-semester Spanish after 34 hours with Duolingo.

Reasons for sketicism

While this is certainly good to see, Duolingo goes a bit far in concluding that this means Duolingo is more effective than a university. It might be true, but these aren't the kind of data you would want to show it. What we would want to know is how much the participants in this study would have learned if they had taken one semester of college Spanish. I doubt the answer is "exactly enough to place into 2nd-Semester Spanish on the study's placement test."One reason is that placement tests are designed to tell you whether someone has enough background to take a class, not whether they know exactly as much as the typical student starting that class. A second reason is that the study population is very different from your typical undergrad. In fact, nearly 3/4 of them had graduated from college already, and over 1/4 had a graduate degree. These are people who are highly experienced at education and who have been very successful, and either reason might make you expect them to learn faster than your typical college freshman. Then there's the fact that the study doesn't seem to control for whether they are using any other methods to learn Spanish at the same time (like taking a class).

I suppose my main reason for being skeptical is that while I find Duolingo incredibly useful for learning nouns and adjectives and for practicing what I already know, I've found it less useful in terms of learning grammar or learning verbs. Grammar is not explicitly taught at all (you're suppose to work out the rules of grammar from seeing example sentences). There are a lot of Spanish verbs with irregular endings, and Duolingo gives you no information about those (except what you might glean from seeing an example sentence with such a verb).

Perhaps this is closer to how children learn (though not really -- Duolingo is all about translation, and generally children don't learn their first language by learning how to translate it into another language!), but I suspect there's a reason that language classes the world over explicitly teach you grammar rules. Babies might not need it, but adults seem to.

What Duolingo is good for

This doesn't mean I've got it in for Duolingo. As I said, I've been using it and intend to keep on using it. Much of Duolingo consists of trying to create new sentences in Spanish and then getting feedback on whether you did it right or not. This is fantastic practice, maybe even better than what you'd get in an immersion environment (in which you create sentences but don't always get feedback), and I highly recommend it to anyone trying to revive moribund language skills or as an addition to an ongoing course of study. I just don't see it standing all by itself.

The other useful tidbit from this study: Most people who started using Duolingo quit, and quit quickly. Which is a reminder that the limiting factor in language learning is not what textbook or website you use, but your own dedication.
Chemistry has its own problems with replication, according to Nature:
Scrounging chemicals and equipment in their spare time, a team of chemistry bloggers is trying to replicated published protocols for making molecules. The researchers want to check how easy it is to repeat the recipes that scientists report in papers ... Among the frustrations [chemists] have experienced with the chemical literature ... are claims that reactions yield products in greater amounts than seem reasonable, and scanty detail about specific conditions in which to run reactions. In some cases, reactions are reported which seem to good to be true - such as a 2009 paper which was corrected within 24 hours by web-savvy chemists live-blogging the experiment.
It's hard to tell from the article how common it is for a reaction simply not to be possible at all as opposed to simply produce less product than reported. Presumably either is problematic, but the causes would be different.

Given the recent excitement about (non-)replication, one has to wonder if this problem is more or less common than in the past. While my gut instinct is that replication was probably less of a problem in the earlier, smaller days of science, it's also quite possible that it's like many forms of violent crime: extremely rare today by historical standards, but we care much more about it.

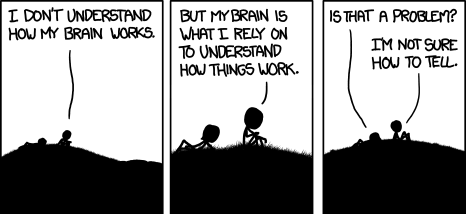
What makes psychology and neuroscience hard

Explained by today's XKCD:


Ambrose Bierce pointed out the same problem in his 1911 satyrical dictionary (The Devil's Dictionary):
Mind, n. A mysterious form of matter secreted by the brain. Its chief activity consists in the endeavor to ascertain its own nature, the futility of the attempt being due to the fact that it has nothing but itself to know itself with. 

Fractionating IQ

Near the dawn of the modern study of the mind, the great psychological pioneer Charles Spearman noticed that people who are good at one kind of mental activity tend to be good at most other good mental activities. Thus, the notion of g (for "general intelligence") was born: the notion that there is some underlying factor that determines -- all else equal -- how good someone is at any particular intelligent task. This of course fits folk psychology quite well: g is just another word for "smarts".

The whole idea has always been controversial, and many people have argued that there is more than one kind of smarts out there (verbal vs. numeric, logical vs. creative, etc.). Enter a recent paper by Hampshire and colleagues (Hampshire, HIghfield, Parkin & Owen, 2012) which tries to bring both neuroimaging and large-scale Web-based testing to bear on the question.

In the neuroimaging component, they asked sixteen participants to carry out twelve difficult cognitive tasks while their brains were scanned and applied principle components analysis (PCA) to the results. PCA is a sophisticated statistical method for grouping things.

A side note on PCA

If you already know what PCA is, skip to the next section. Basically, PCA is a very sophisticated way of sorting thigns. Imagine you are sorting dogs. The simplest thing you could do is have a list of dog breeds and go through each dog and sort it according to its breed.

What if you didn't already have dog breed manual? Well, German shepherds are more similar to one another than any given German shepherd is to a poodle. So by looking through the range of dogs you see, you could probably find a reasonable way of sorting them, "rediscovering" the various dog breeds in the process. (In more difficult cases, there are algorithms you could use to help out.)

That works great if you have purebreds. What if you have mutts? This is where PCA comes in. PCA assumes that there are some number of breeds and that each dog you see is a mixture of those breeds. So a given dog may be 25% German Shepherd, 25% border collie, and 50% poodle. PCA tries to "learn" how many breeds there are, the characteristics of those breeds, and the mixture of breeds that makes up each dog -- all at the same time. It's a very powerful technique (though not without its flaws).

Neuroimaging intelligence

Analysis focused only on the "multiple demands" network previously identified as being related to IQ and shown in red in part A of the graph below. PCA discovered two underlying components that accounted for about 90% of the variance in the brain scans across the twelve tasks. One was particularly important for working memory tasks, so the authors called in MDwm (see part B of the graph below), and it involved mostly the IFO, SFS and ventral ACC/preSMA (see part A below for locations). The other was mostly involved in various reasoning tasks and involved more IFS, IPC and dorsal ACC/preSMA.


Notice that all tasks involved both factors, and some tasks (like the paired associates memory task) involved a roughly equal portion of each.

Sixteen subjects isn't very many

The authors put versions of those same twelve tasks on the Internet. They were able to get data from 44,600 people, which makes it one of the larger Internet studies I've seen. The authors then applied PCA to those data. This time they got three components, two of which were quite similar to the two components found in the neuroimaging study (they correlated at around r=.7, which is a very strong correlation in psychology). The third component seemed to be particularly involved in tasks requiring language. Most likely that did not show up in the neuroimaging study because the neuroimaging study focused on the "multiple demands" network, whereas language primarily involves other parts of the brain.

The factors dissociated in other ways as well. Whereas people's working memory and reasoning abilities start to decline about the time people reach the legal drinking age in the US (coincidence?) verbal skills remain largely undiminished until around age 50. People who suffer from anxiety had lower than average working memory abilities, but average reasoning and verbal abilities. Several other demographic factors similarly had differing effects on working memory, reasoning, and verbal abilities.

Conclusions

The data in this paper are very pretty, and it was a particularly nice demonstration of converging behavioral and neuropsychological methods. I am curious what the impact will be. The authors are clearly arguing against a view on which there is some unitary notion of IQ/g. It occurred to me as I wrote this what while I've read many papers lately discussing the different components of IQ, I haven't read anything recent that endorses the idea of a unitary g. I wonder if there is anyone, and, if so, how they account for this kind of data. If I come across anything, I will post it here.


------
ResearchBlogging.orgHampshire, A., Highfield, R., Parkin, B., & Owen, A. (2012). Fractionating Human Intelligence Neuron, 76 (6), 1225-1237 DOI: 10.1016/j.neuron.2012.06.022

Professor -- The Easiest Job in the World

There has been a small kerfuffle over Susan Adams's article at Forbes, titled "The least stressful jobs of 2013":
University professors have a lot less stress than most of us. Unless they teach summer school, they are off between May and September and they enjoy long breaks during the school year, including a month over Christmas and New Year's and another chunk of time in the spring. Even when school is in session they don't sped too many hours in the classroom ... Working conditions tend to be cozy and civilized and there are minimal travel demands...
She also mentions the great job prospects ("Universities are expected to add 305,700 adjunct and tenure-track professors by 2020").

To her credit, Adams has added a sizable addendum to her article, correcting -- but not apologizing for -- her mistakes. Unfortunately, this is far from the first time this kind of article has appeared in a major publication. Some time back, a columnist for the New York Times wrote an article suggesting that the solution to rising costs of higher education was to make professors work more than a few hours a week. An article in the New Yorker casually noted that the new head of a particular company was concerned that his employees worked "the hours of college professors" (I initially assumed they meant "way too hard" and that the boss wanted them to take a break!). What gives?

Scicurious suggests it's the curse of half-knowledge:
The vast majority of us aren't teachers or professors, but we've all been students, right? ... We thought that, because of what we saw of them in our classes, we knew what they did ... Because of this half-knowledge, people make assumptions about our jobs, assumptions that can really affect how we are perceived as people...
 That is no doubt part of it, but it also requires that people not think very hard. If I heard that someone made a pretty good living working only a few hours a week, it would immediately set off my implausibility alarm. I mean, what are the chances? And you'd only have to think for a moment to realize this can't be true.

Adams got hundreds of comments and letters pointing out that professors, in addition to giving a few lectures a week, also grade papers, advise students, write papers and books, go to conferences, give invited talks, etc. Adams presents this as if this came as a surprise, but that seems equally implausible. I'm going to assume she's read one or two articles about medicine or science, in which case the people discussed are inevitably professors. In fact, articles about politics occasionally cite professors as well. If she went to college, she knows that professors have office hours and grade papers. Many of the books on science and politics in the bookstore are written by faculty, as are essentially all college textbooks.

Even if she had never attended college, never interacted with a professor, and didn't read articles about higher education, a few minutes of Googling prior to writing her article would have corrected that mistake. My guess is that she didn't really think about her article before writing it and didn't consult either her own memory or Google because she -- and the others who write similar articles -- wanted this crazy claim about the lazy professor to be true. The interesting question is why she wanted it to be true. Anti-intellectualism? A desire to believe that such cushy jobs really exist? Or is this just an example of one of those ideas that are crazy enough that they inspire belief (like one of those many apocryphal "weird facts")?

*I do realize that some professors do very little work. Some people in all professions do very little work.

Transferring Consciousness

My brother was just in town, and we had our usual argument about Old Man's War, which he loves and about which I'm less enthusiastic (it was a fun read, but...). Perhaps one issue that keeps me from enjoying it fully is that whenever I think about it I think about an early scene, in which a character's consciousness was transferred from an old body to a new body. This is presented in the book as just one more futuristic miracle, but I can't stop thinking about the deeper questions it raises.

What does it mean to transfer consciousness from one body to another? Our current scientific understanding is that there is no consciousness separate from the underlying physical machinery, so such a transfer could not happen. But you might be able to create the illusion of a consciousness transfer, which I explain below. So we can make sense of Old Man's War if we assume that the doctors are deliberately lying about what is going on, covering up the murder that lies at the heart of the procedure.

Here's what might be going on (yes, I realize this is fiction, but good science fiction almost always has a thought experiment at its heart): It should be possible, at least in principle, to create a new body that has identical machinery to an existing body. This is would be new person who is a twin not only physically but mentally, down to having the same memories (by definition, since they have the same brains down to the microcircuitry). From the new person's perspective, he has finds herself suddenly in a "new" body. (This is much like the old philosophical puzzle, what if the world was created yesterday, all of us with artificial memories?)

So now we've got a consciousness that believes itself to have transferred into a new body from an old body. What happened to the consciousness in the old body? The doctors in Old Man's War claim that it is now a vegetable, with no consciousness inside, because that consciousness has transferred. Since that can't happen, they are lying: either the process of creating the new copy of the old brain destroys the old brain, or the doctors deliberately destroy the old brain to preserve the illusion of the transfer (after all, if transfer is impossible, why go through this procedure? It's very nice for your twin to have a new body, but it's not going to do you any good at all!).

Here's the question: does this matter? If John undergoes this procedure happens on a Wednesday, then the world on Thursday is much the same as the world on Tuesday: on both days, there is a consciousness calling itself "John" with roughly the same memories. It only gets tricky when you think too much about Wednesday. You might be tempted to say you have John 1 on Tuesday and John 2 on Thursday, who are duplicates but nonetheless not the same because they have different bodies. But, of course, John had a different body when he was 5yo than when he was 75yo, down even to being made up of different atoms. So if we're willing to call 5yo John and 75yo John the same person, why aren't John 1 and John 2?

This confuses the heck out of me, which is why I have difficulty paying attention to the novel itself.